01 / Featured project
Slash Horror
A place to find your next scare and keep track of what you’ve watched.
- Node.js
- Express
- Handlebars
- Neon Auth
- PostgreSQL
- APIs
- Selenium
- Beautiful Soup
01 / The idea
Make horror easier to explore.
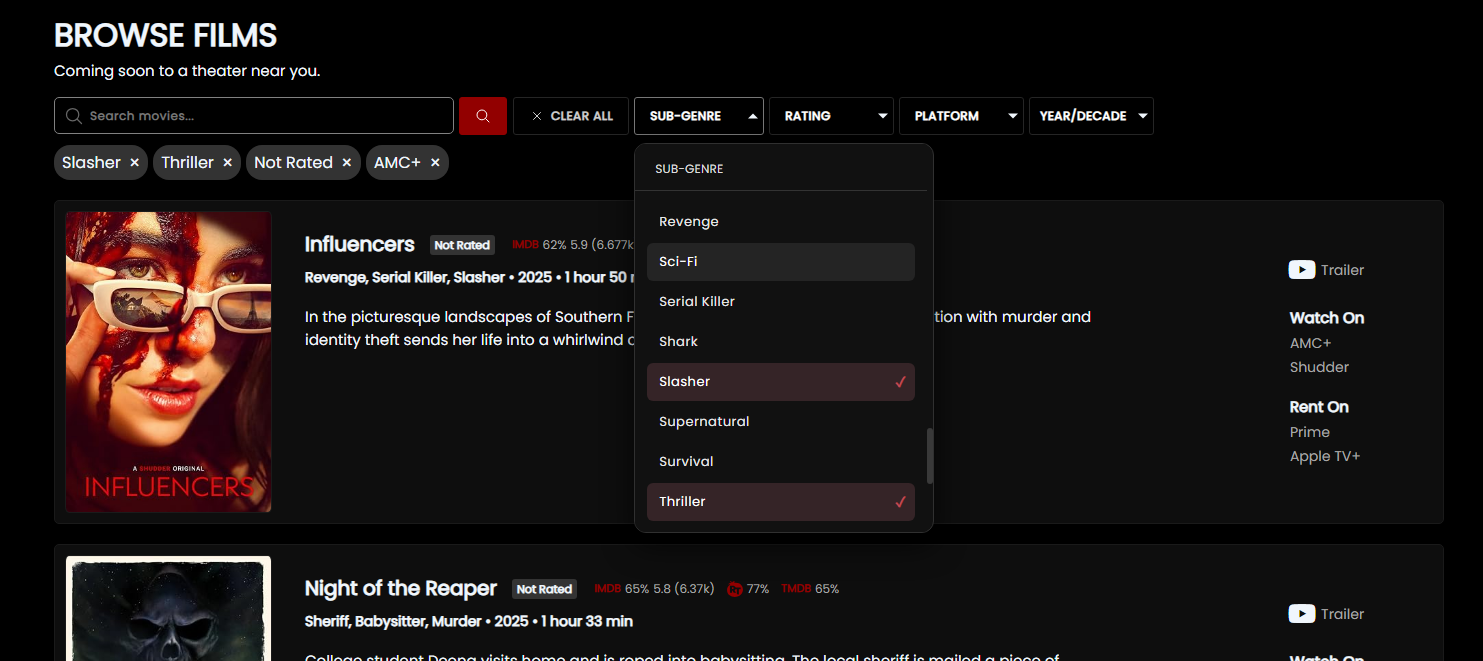
I built Slash Horror around the way I look for something to watch. I wanted to be able to follow a franchise, browse a subgenre, or find more from a director without starting a new search every time. The site gives films and TV their own sections and lets signed-in users track, rate, and review what they find.
02 / The architecture
A catalog and a community, stored separately.
I moved Slash Horror’s account features from Firebase to Neon Auth and PostgreSQL while keeping the curated film and TV catalog in JSON. Neon Auth handles sign-in, and PostgreSQL stores profiles, viewing activity, custom lists, reviews, and follows. The imdb_id field links title-specific activity back to
the catalog, so I can update a film’s metadata without copying the
catalog into the database or touching anyone’s watch history.
03 / The details
A rating should do double duty.
When someone gives a title a knife rating, the server saves the rating, marks the title as watched, and removes it from their watchlist in a single SQL transaction. That means the changes succeed together or roll back together. For TV, I kept “currently watching” separate from “watched,” so someone can rate a show they’ve started without marking it finished.
04 / The community
Make it your own, then see what other fans are watching.
I built profiles that bring favorites, watchlists, ratings, and custom lists together. Members can make their profiles private or go public so other fans can follow them. Film, TV, and blog discussions support threaded replies and likes, with in-app notifications for replies, likes, and new followers.
05 / The build
Make the catalog searchable.
I built a Python data pipeline that pulls film and TV metadata from the TMDB and OMDb APIs, uses IMDb IDs to match titles across sources, and adds streaming and rental availability to the JSON catalog. To collect data from web pages, I use Selenium to load the pages and Beautiful Soup to parse the HTML and extract the fields I need.
I built separate Express search routes for films and for the
/tv section, then used Handlebars to render results from
the JSON catalog. I normalize titles and keywords when matching a query,
so differences in capitalization and punctuation don't require edits
to the source records. TV searches can match any year in a show's
run, while film searches match the release year. Subgenre links use
the genre: filter to take you straight from a title page
to related results without typing another search.